Prepaid GPU-hour packs across the Hugging Face Hub: code and math models, embeddings and retrieval, speech and audio, translation, efficient architectures and multimodal vision. Every pack is a virtual product - no shipping, and an endpoint key is issued once the order completes.
New
Brand: Hugging Face
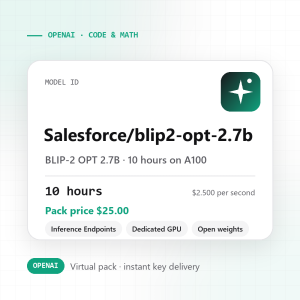
BLIP-2 OPT 2.7B · 10 hours on A100 - a prepaid inference-hour pack for Salesforce/blip2-opt-2.7b, billed at Hugging Face's published Inference Endpoints rate of $2.50 per hour on A100 80GB.What you get10 hour(s) of dedicated A100 80GB inference.The model loaded from the Hub: Salesforce/blip2-opt-2.7..
$25.00
New
Brand: Hugging Face
Jina Embeddings v3 · 10 hours on T4 - a prepaid inference-hour pack for jinaai/jina-embeddings-v3, billed at Hugging Face's published Inference Endpoints rate of $0.50 per hour on T4 16GB.What you get10 hour(s) of dedicated T4 16GB inference.The model loaded from the Hub: jinaai/jina-embeddings-v3.N..
$5.00
New
Brand: Hugging Face
Mamba 2.8B · 10 hours on A100 - a prepaid inference-hour pack for state-spaces/mamba-2.8b, billed at Hugging Face's published Inference Endpoints rate of $2.50 per hour on A100 80GB.What you get10 hour(s) of dedicated A100 80GB inference.The model loaded from the Hub: state-spaces/mamba-2.8b.No ship..
$25.00
New
Brand: Hugging Face
MetaMath 7B · 10 hours on L4 - a prepaid inference-hour pack for meta-math/MetaMath-7B-Instruct, billed at Hugging Face's published Inference Endpoints rate of $0.80 per hour on L4 24GB.What you get10 hour(s) of dedicated L4 24GB inference.The model loaded from the Hub: meta-math/MetaMath-7B-Instruc..
$8.00
New
Brand: Hugging Face
Multilingual E5 Large · 10 hours on T4 - a prepaid inference-hour pack for intfloat/multilingual-e5-large, billed at Hugging Face's published Inference Endpoints rate of $0.50 per hour on T4 16GB.What you get10 hour(s) of dedicated T4 16GB inference.The model loaded from the Hub: intfloat/multilingu..
$5.00
New
Brand: Hugging Face
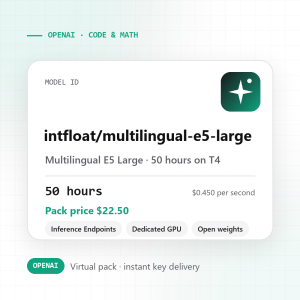
Multilingual E5 Large · 50 hours on T4 - a prepaid inference-hour pack for intfloat/multilingual-e5-large, billed at Hugging Face's published Inference Endpoints rate of $0.50 per hour on T4 16GB.What you get50 hour(s) of dedicated T4 16GB inference.The model loaded from the Hub: intfloat/multilingu..
$22.50
New
Brand: Hugging Face
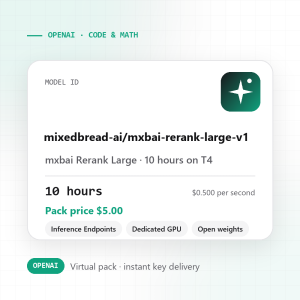
mxbai Rerank Large · 10 hours on T4 - a prepaid inference-hour pack for mixedbread-ai/mxbai-rerank-large-v1, billed at Hugging Face's published Inference Endpoints rate of $0.50 per hour on T4 16GB.What you get10 hour(s) of dedicated T4 16GB inference.The model loaded from the Hub: mixedbread-ai/mxb..
$5.00
New
Brand: Hugging Face
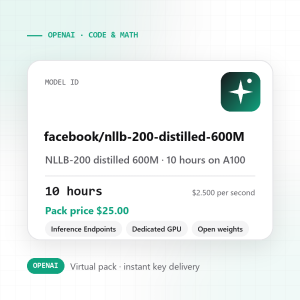
NLLB-200 distilled 600M · 10 hours on A100 - a prepaid inference-hour pack for facebook/nllb-200-distilled-600M, billed at Hugging Face's published Inference Endpoints rate of $2.50 per hour on A100 80GB.What you get10 hour(s) of dedicated A100 80GB inference.The model loaded from the Hub: facebook/..
$25.00
New
Brand: Hugging Face
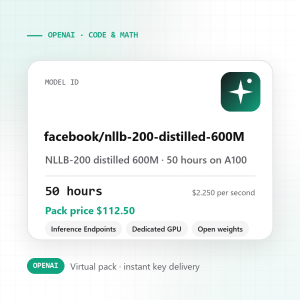
NLLB-200 distilled 600M · 50 hours on A100 - a prepaid inference-hour pack for facebook/nllb-200-distilled-600M, billed at Hugging Face's published Inference Endpoints rate of $2.50 per hour on A100 80GB.What you get50 hour(s) of dedicated A100 80GB inference.The model loaded from the Hub: facebook/..
$112.50
New
Brand: Hugging Face
Phi-2 · 10 hours on L4 - a prepaid inference-hour pack for microsoft/phi-2, billed at Hugging Face's published Inference Endpoints rate of $0.80 per hour on L4 24GB.What you get10 hour(s) of dedicated L4 24GB inference.The model loaded from the Hub: microsoft/phi-2.No shipping: the endpoint key is i..
$8.00
New
Brand: Hugging Face
Qwen2.5-Coder 7B · 10 hours on L4 - a prepaid inference-hour pack for Qwen/Qwen2.5-Coder-7B-Instruct, billed at Hugging Face's published Inference Endpoints rate of $0.80 per hour on L4 24GB.What you get10 hour(s) of dedicated L4 24GB inference.The model loaded from the Hub: Qwen/Qwen2.5-Coder-7B-In..
$8.00
New
Brand: Hugging Face
Qwen2.5-Coder 7B · 50 hours on L4 - a prepaid inference-hour pack for Qwen/Qwen2.5-Coder-7B-Instruct, billed at Hugging Face's published Inference Endpoints rate of $0.80 per hour on L4 24GB.What you get50 hour(s) of dedicated L4 24GB inference.The model loaded from the Hub: Qwen/Qwen2.5-Coder-7B-In..
$36.00